Ontomark
Ontologies in Markdown: index typed notes, run local OWL 2 EL reasoning and SPARQL, apply reviewed frontmatter edits, and optionally extract facts with a model you choose. Offline by default
- Overview
- Scorecard
- Updates9
Make your vault mean something to a machine, without changing how you write. Add a type and a parent link to a note's frontmatter and Ontomark turns your vault into an ontology: it draws the hierarchy, works out what follows from it, answers precise questions about it, and shows every proposed change as a diff before anything is written. Notes stay plain Markdown. Nothing leaves your computer unless you choose to connect a model.
https://github.com/user-attachments/assets/5a129220-975a-4ac9-b501-d2b0365022cb
Quick tour (2:09): graph, ontology panel, SPARQL queries and reviewed edits. Open the video issue.
Why bother?
Backlinks tell you two notes are related. They cannot tell you how. An ontology can: Rex is a Dog, Dog is a kind of Animal, so Rex is an Animal, and anyone, human or agent, asking "which animals are in this vault?" gets Rex without you ever writing that down.
That matters most when a vault grows past what you can hold in your head, and when you start pointing AI tools at it. A model reading prose sees words that happen to sit together. A model reading a typed graph gets facts it can follow, check and cite. Ontomark gives your vault that layer, locally.
Three notes is enough to start
# Animal.md
---
type: class
---
# Dog.md
---
type: class
subclass-of: ["[[Animal]]"]
---
# Rex.md
---
type: individual
instance-of: ["[[Dog]]"]
---
Open Ontology graph. Solid edges are what you wrote; the dashed Rex → Animal edge is what the reasoner worked out. No folder layout, no special syntax beyond three frontmatter keys.
What you get
| Ontology graph | Explore typed notes and their hierarchy. Search, zoom, focus a neighbourhood, open the note. Inferred edges are dashed. |
| Ontology panel | Browse classes, individuals and properties; see stated and inferred parents, and anything the reasoner could not handle. |
| Local reasoning | An OWL 2 EL reasoner runs inside Obsidian and keeps up as you edit. Nothing is approximated: if a construct is unsupported, it says so. |
| SPARQL | Ask structured questions (SELECT, ASK, CONSTRUCT) over what you stated, what was inferred, or both. A working example is loaded for you. |
| SPARQL in a note | Put a query in an ontomark-sparql code block and it renders its result there, live. __THIS__ is the note it sits in and [[Note]] is any entity note; # dataset: combined includes what was inferred. After Dot Triples. |
| Reviewed edits | Commands to make a note a class, individual or property, or add a parent. Every change is a diff you apply, and is refused if the file changed underneath it. |
| Assisted ingest | Point the plugin at a model endpoint of your choosing, enter a key for the session, and run Extract facts from this note. The model suggests; the engine checks every suggestion against your vault and the note's own text; you see a diff with each quote beside its fact, and the refusals with their reasons, and decide. Off by default: nothing is sent until you set an endpoint, and then only to that one URL, only when you run the command. |

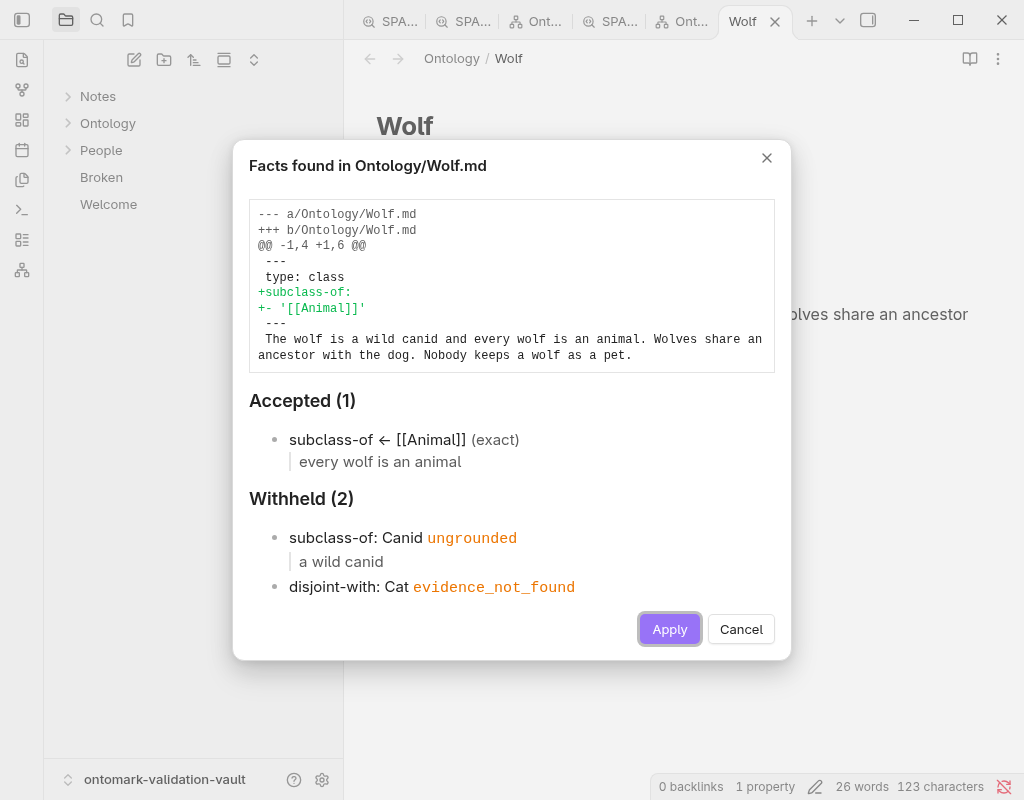
Every count in the drawing comes from one six-note example vault (docs/figures/anatomy-src/model.mjs); the build fails if the drawing stops matching it. Ingest is drawn switched on; it is off by default and does nothing until you set an endpoint. The figure follows your system's light or dark setting.
About assisted ingest
Language models are good at reading a note and bad at being trusted with your ontology: they invent identifiers, merge things that share a name, and quote text that is not there. Ontomark's ingest lets the model do only the reading.
- The model receives the note's text, its label and the keys it may fill. Never other notes, never your vault path, never your API key.
- The engine grounds every proposed name against the labels and aliases already in your vault; the model's own identifiers are ignored. A name that fits two notes is withheld as ambiguous, not guessed.
- Every value needs a verbatim quote from the note, and the quote has to mention the value. Literals are checked against their types (
3,5is not a decimal;2023-02-29is not a date). - Everything accepted becomes one patch, shown as the usual diff with the evidence highlighted. Everything refused is listed with the reason. Apply is the normal reviewed-edit path; undo is Obsidian's undo.
One endpoint, the one you type in, is the only place the plugin can send anything, and only when you run the command. Type the final URL: Obsidian's request layer follows redirects on its own, so the plugin refuses a 3xx answer rather than letting a hop choose the destination for you. ADR-OBS-003 is the full decision.
SPARQL in a note
A query that is about a note belongs in that note. In reading view, this block shows every type Rex has, stated or inferred:
```ontomark-sparql
# dataset: combined
PREFIX rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#>
SELECT ?type WHERE { __THIS__ rdf:type ?type } ORDER BY ?type
```
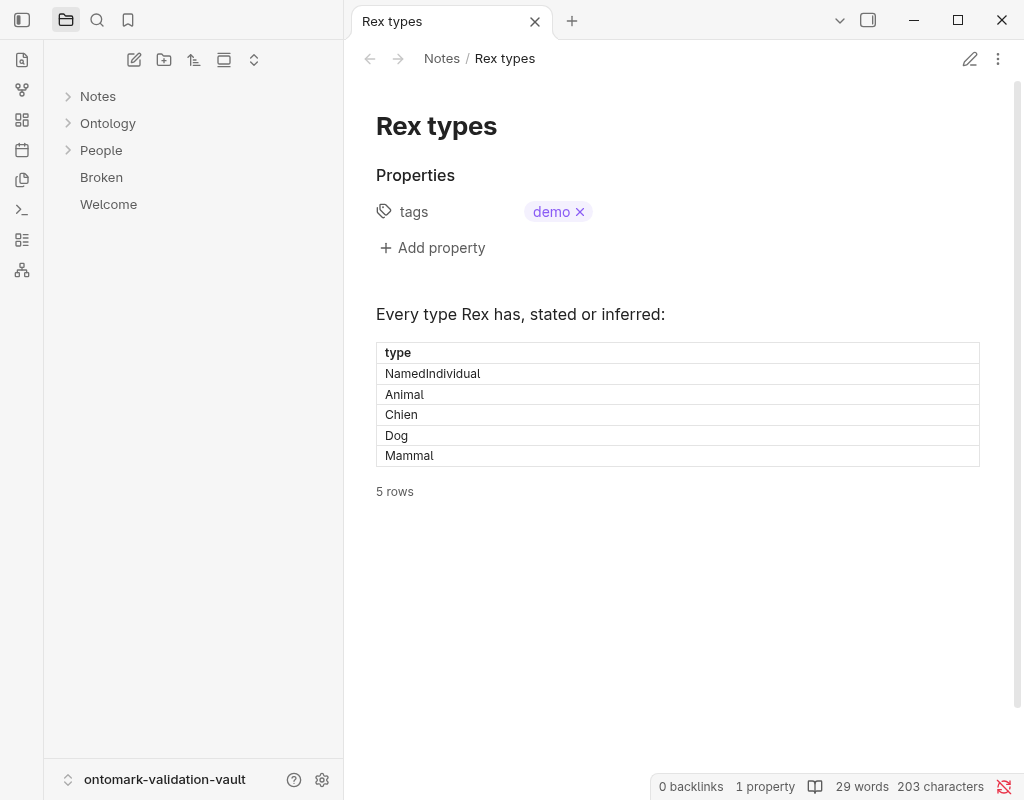
__THIS__ is the note the block sits in; [[Dog]] or [[Dog|the dog]] is that note's entity; the first comment may pick the dataset. The query is plain SPARQL otherwise, so it pastes into the SPARQL view or any other engine unchanged. A reference that does not resolve stops the block with a reason, and nothing runs. The in-note surface and its two tokens follow Cristian Vasquez's Dot Triples, with one difference: references inside string literals and comments are left alone (ADR-OBS-004).
Why it works
A few numbers from the research this rests on:
- Asking a model questions over a knowledge graph instead of the raw database schema took GPT-4's accuracy on enterprise questions from 16% to 54% (Sequeda, Allemang & Jacob, 2023, arXiv:2311.07509).
- Letting the model propose names and grounding them against a real vocabulary afterwards returned the correct ontology identifier for 98 of 100 terms; asking the model for identifiers directly got 3 of 100 (SPIRES, Caufield et al., Bioinformatics 2024, arXiv:2304.02711). That is the pattern Ontomark's ingest follows.
- Left to their own devices, models fabricate: 55% of GPT-3.5's and 18% of GPT-4's literature citations in one study did not exist (Walters & Wilder, Scientific Reports 2023, doi:10.1038/s41598-023-41032-5). Hence a diff you review, not an edit you discover.
- The reasoning is cheap by design. OWL 2 EL keeps classification polynomial even with general axioms (Baader, Brandt & Lutz, IJCAI 2005), which is how an EL reasoner classifies SNOMED CT's ~300,000 concepts in under ten seconds (Kazakov, Krötzsch & Simančík, J. Automated Reasoning 2014). A vault is a great deal smaller.
Two things make the approach sound rather than hopeful. OWL 2 EL is the fragment of the Web Ontology Language built for large class hierarchies: classification is polynomial, which is why terminologies with hundreds of thousands of classes use it and why it can run inside an editor. And grounding is a separate, deterministic step: following the SPIRES pattern (Caufield et al., OntoGPT), the model proposes names and the engine resolves them against your real vocabulary, so a model error becomes a withheld suggestion rather than a wrong fact.
Under the hood
Under the plugin sits Ontomark, a Rust workspace (parser, typed model, whelk-el reasoner, RDF/SPARQL compiler, ingest) compiled to WebAssembly and embedded in the plugin, running in a background worker. The graph view is the shared ontomark-graph package. The plugin itself is TypeScript, built with esbuild against the Obsidian API, and its release gate runs the built plugin in a Docker container with networking disabled and a tripwire on any socket, DNS or fetch.
Limits worth knowing. Desktop only for now. Reasoning covers the implemented part of OWL 2 EL (no property-range reasoning, no broader individual-level reasoning); unsupported constructs mark the result incomplete. Very large vaults fall back to a relevant-only classification policy and say so. SPARQL refuses UPDATE, SERVICE, FROM and DESCRIBE, and caps rows and time. Ingest proposes facts against the vocabulary you already have; it will not invent classes, and the guards decide what is safe to write, not what is true, which is why you review. Until you set an endpoint, the plugin makes no network requests at all; its release tests run it in a container with networking disabled. Inline key :: value fields are not read, on purpose: only frontmatter asserts, so a diff is the whole review. If you want every field and link in your vault as RDF, Dot Triples does that, and Ontomark's bridge joins the two graphs.
How it does on a real corpus
My own main vault is a public knowledge graph of 8,446 typed notes (AI, governance, XR and more), published at narrativegoldmine.com with its live graph, kept to a stricter frontmatter spec, the VisionFlow corpus contract: every page has a stable resource IRI, is-a parents, a public gate and provenance. The plugin's optional Estate corpus profile reads that spec directly. Running the v0.2.0 engine over the whole vault (the figures below predate the plugin's current engine; later releases changed only the frontmatter parser and diagnostics, not the reasoner), on an ordinary laptop (Intel i7-1165G7, 16 GB, Obsidian 1.14.4):
- all 8,446 notes indexed as entities, 278k triples in about 2 s;
- full classification in about 1.5 s, complete, no unsatisfiable classes, about 58k subclass links in the combined graph;
- and real problems surfaced in the data: 935 ambiguous parent links (a
[[Decentralized Autonomous Organization]]that matches both DAO and the full-name note), 936 parents pointing at pages that do not exist, and 42 accidentalis-acycles that quietly make two classes one (automation ≡ smart-home was the author's favourite). Cleanup is in progress.
Ontomark's engine README reports the same corpus through its command-line build, which applies a different public gate and so counts 9,244 classes; the two figures measure different things, not a disagreement.
Install
Ontomark is in the community directory: Settings → Community plugins → Browse, search for Ontomark, or open obsidian://show-plugin?id=ontomark.
To install by hand instead:
- Download ontomark-obsidian-0.3.3.zip from the 0.3.3 release.
- Extract it into
<vault>/.obsidian/plugins/; it creates anontomarkfolder. - Settings → Community plugins, enable Ontomark, reload if Obsidian was open.
Each release ships with the engine inside it: no Node, Rust, account, database or internet connection is needed.
Frontmatter reference
Only notes with type: class, type: individual or type: property become ontology entities. Everything else stays a plain note. Prose wikilinks are never assertions.
| Key | Meaning |
|---|---|
type |
class, individual or property |
title, aliases |
Display name and other labels (also what ingest grounds against) |
iri |
Optional explicit identifier; otherwise derived from the note path |
subclass-of / is-a |
Parent class |
equivalent-to, disjoint-with |
Equivalent or mutually exclusive classes |
instance-of |
Class of an individual |
domain, range, subproperty-of |
Property description and hierarchy |
Write relations as a list of quoted links: subclass-of: ["[[Animal]]"], or one - "[[Animal]]" per line. Ontomark reads a single quoted link too, but Obsidian stores that as text, so list filters in Bases such as note["subclass-of"].contains(this.file.asLink()) skip it; the panel notes it as info. (Bases needs the note["…"] form for a hyphenated property: a bare subclass-of.contains(…) is read as subtraction and matches nothing.) An unquoted [[Animal]] is read by YAML as a nested list, so quote it.
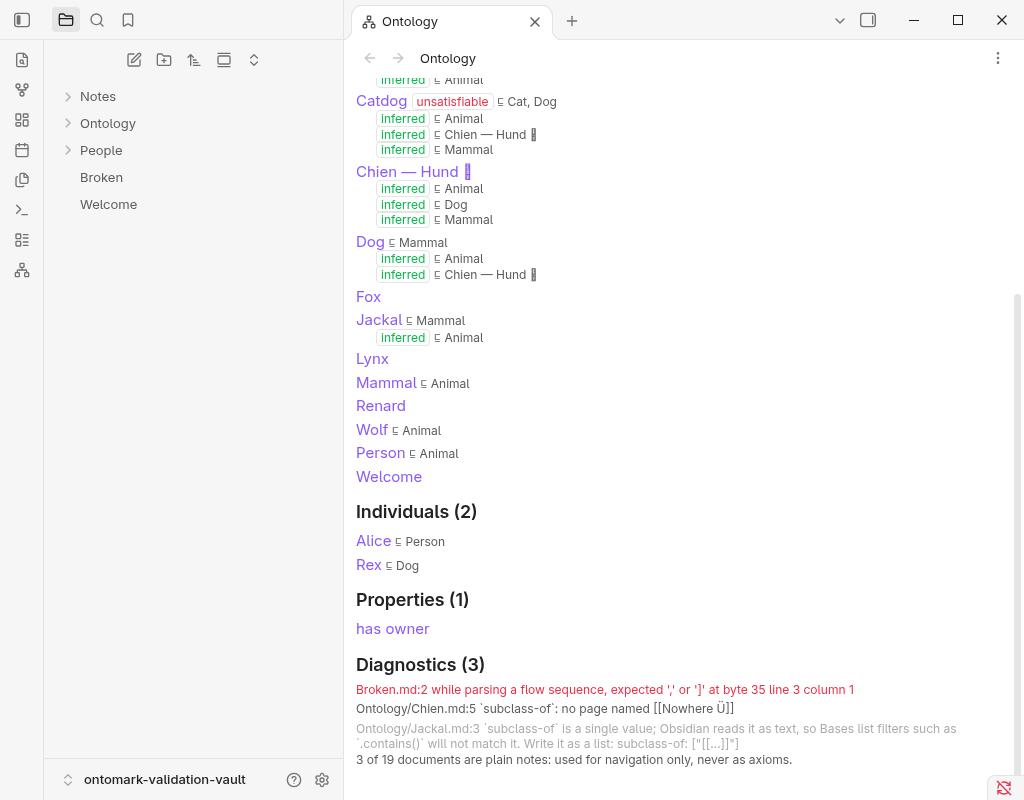
Other keys are kept as annotations. The default Generic profile works in any vault; the optional Estate corpus profile is for corpora that follow the VisionFlow contract.
Further afield
This repository is only the Obsidian interface. If you want to go deeper:
- Ontomark: the engine, CLI, shared graph, and the measured case for structured knowledge made on a 9,000-note corpus.
- VisionFlow: the wider project on making human-written knowledge useful to agents.
- Dot Triples by Cristian Vasquez: every note, field and link in a vault as RDF, queried with SPARQL. The in-note query block here follows it, and the engine's bridge lifts its output into Ontomark's vocabulary.
- Local decisions: ADR-OBS-001, ADR-OBS-002, ADR-OBS-003, ADR-OBS-004; desktop acceptance record.
Build and test from source
Node 22 or later. The build fetches the pinned Ontomark engine and verifies its SHA-256; no Rust toolchain is required.
npm ci --include=dev
npm run build
npm run check:bundle
npm test
npm run test:wasm
npm run test:offline
Licence
MIT OR Apache-2.0. The release ZIP includes third-party notices; upstream credits cover the engine's components.