Speech Kit
 Alexander Brittain7k downloads
Offline and private speech-to-text, text-to-speech, and translation for desktop notes. Dictate notes, transcribe meetings, and more. NVIDIA, Whisper, and natural voices running on your machine.
- Overview
- Scorecard
- Updates39

Dictate live. Transcribe audio and video files. Bring YouTube captions into your notes. Translate text. Listen to notes. One plugin inside the editor where your notes already live.
Local Dictation is now Speech Kit. It is the same plugin with the same local-first foundation, now with a name that fits what it has become. Existing installs, settings, and hotkeys carry over automatically.
Install Speech Kit from Obsidian Community Plugins
What it does
- Dictate: Capture long sessions with live text and a choice of speech models.
- Transcribe files: Drop in audio or video and turn its audio into a local transcript.
- Import YouTube captions: Paste a link and bring available captions into your note without downloading the video.
- Translate and listen: Translate notes locally and hear them read aloud with natural voices.
- Refine with AI: Run a custom preset on a complete transcript or note using a local model or your chosen provider.
Choose the models that fit your workflow
Install the models you need in Settings → Speech Kit → Manage models. Available languages and performance depend on the model and your computer.
| You want | Models to consider |
|---|---|
| English live dictation | Moonshine, English Nemotron, or Parakeet Unified |
| Multilingual live dictation | Nemotron 3.5 ASR |
| File transcription or batch dictation | Whisper, Cohere Transcribe, or Qwen3 ASR |
| Local voices | Pocket TTS or Supertonic 3 |
| Local translation | Firefox Translations or Tencent HY-MT 2 |
The setup wizard helps you install the native engine and your first speech model. Review each model’s download size and license before installing it. NVIDIA streaming models run on CPU; performance and delay depend on your computer.
Dictate, transcribe, translate, listen, and refine
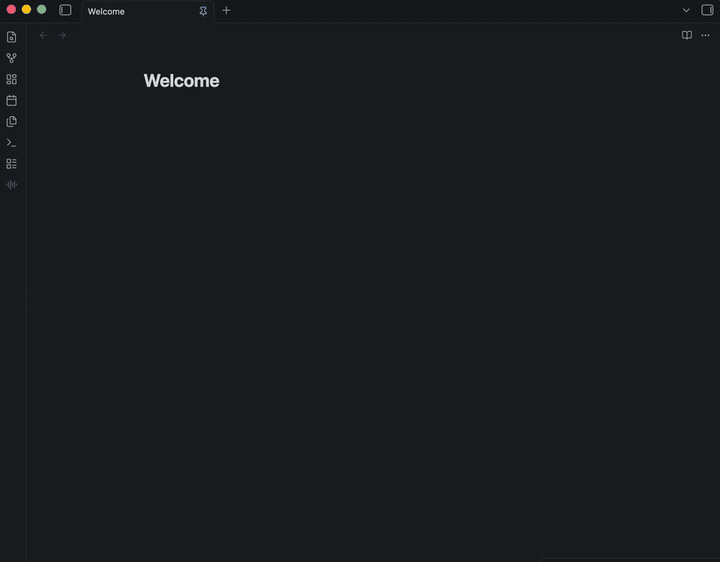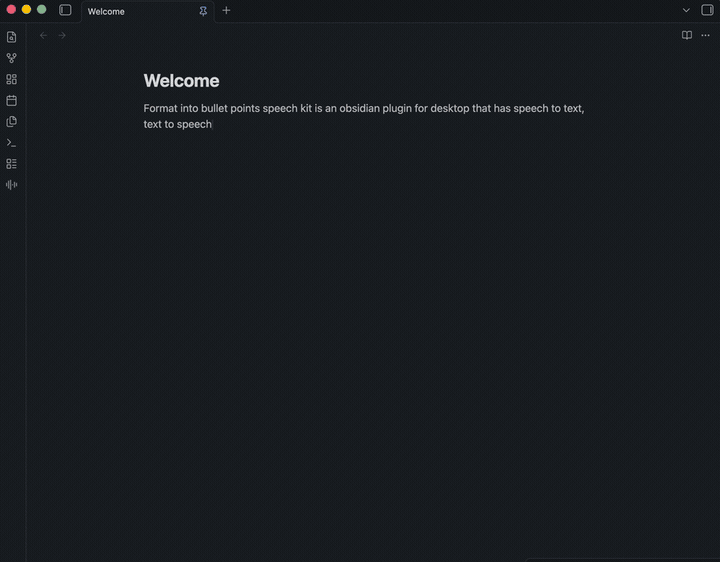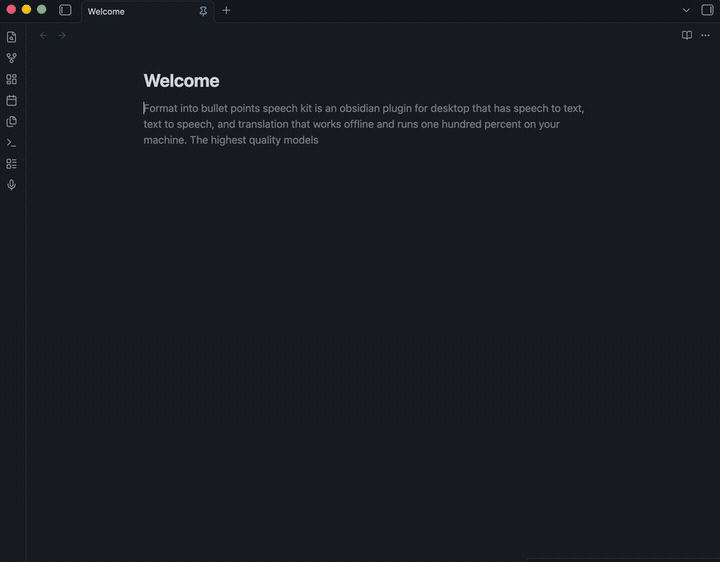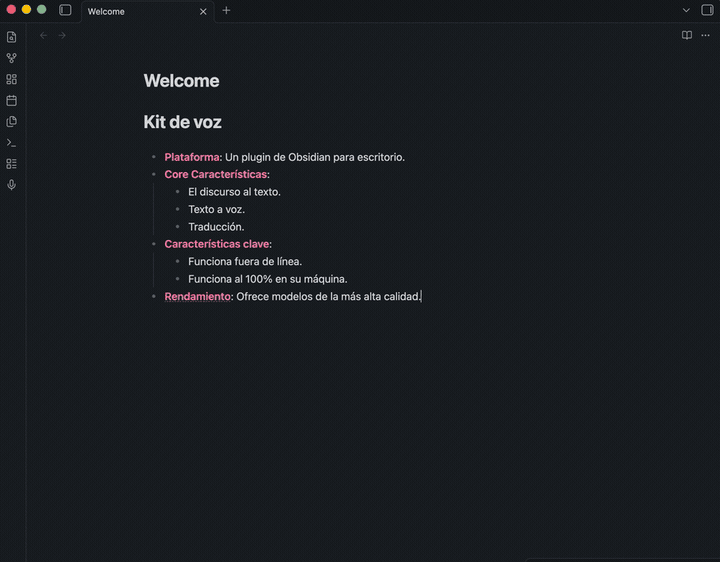
Dictate. Streaming words appear and revise in place while you speak. Finished text lands as Markdown at your cursor. Batch models show results after speech is processed.
Optional desktop dictation controls let you start and stop from a global shortcut or native status menu while another app has focus. Obsidian remains the destination and must stay running.
To keep microphone audio, enable Save microphone recording in Speech Kit settings. It is off by default and does not include system audio. When you stop dictation, Speech Kit saves the recording in Obsidian’s attachment location and adds an audio player to the note. Cancelling dictation discards the unfinished recording. Speech Kit also saves the audio if the sidecar stops the session because of an error or backlog. If the player cannot be added, Speech Kit keeps the recording and shows its link. If the recording itself cannot be completed, Speech Kit removes the incomplete file and shows a warning.
Transcribe files. Run Transcribe local audio file to turn an audio or video recording into text in the current note. Speech Kit extracts the audio with its media decoder and transcribes it with an installed batch speech model. Choose a language, model, timestamps, speaker labels, and paragraph style for that job. Your media stays on your computer.
Import YouTube captions. Run Transcribe YouTube video, paste a video link, and add its available captions to the current note. Choose the caption language and optional linked timestamps. This command needs an internet connection, but no speech model or video download. Videos without usable captions leave the note unchanged.
Both commands can optionally run one of your AI presets on the complete transcript. AI is separate from transcription; if you choose a remote provider, transcript text is sent to that provider. See the media transcription guide for setup and options.
Translate. Translate a selection or a whole note. Firefox Translations supports 96 English-anchored directions. Tencent HY-MT 2 supports direct translation among its 38 catalog languages. Preview the result before replacing your text, inserting it into the note, or copying it.
Listen. Read any note aloud with natural local voices. Control the voice, speed, and playback without leaving Obsidian.
Refine. Optional LLM tools can clean up, summarize, restructure, or transform text with your own prompts.
One toolkit across platforms
Speech Kit supports desktop Obsidian on macOS, Windows, and Linux. Acceleration and system-audio support depend on the platform and model.
| Platform | Architecture | Acceleration | System audio |
|---|---|---|---|
| macOS | Apple silicon | Model-dependent Metal | macOS 14.2 or later |
| Windows | x86-64, ARM64 (Snapdragon 8cx or newer) | Optional NVIDIA CUDA (x86-64 only) | Supported |
| Linux | x86-64, ARM64 glibc (ARMv8.2 or newer, e.g. Raspberry Pi 5) | Optional NVIDIA CUDA (x86-64 only) | PulseAudio or PipeWire |
For Linux and CUDA requirements, see the Linux guide and CUDA guide. Mobile Obsidian is not supported.
Models and acceleration
These are the execution paths in the current source and sidecar build configuration. A released install exposes the models included in its installed sidecar; recent additions may await a release.
| Feature and model family | macOS Apple silicon | Windows x86-64 | Windows ARM64 | Linux x86-64 | Linux ARM64 |
|---|---|---|---|---|---|
| Batch speech · Whisper | CPU / Metal | CPU / CUDA* | CPU | CPU / CUDA* | CPU |
| Batch speech · Qwen3 ASR | CPU / Metal | CPU / CUDA* | CPU | CPU / CUDA* | CPU |
| Live dictation · Moonshine (English) | CPU | CPU | CPU | CPU | CPU |
| Live dictation · Nemotron / Parakeet Unified | CPU | CPU | CPU | CPU | CPU |
| Batch speech · Cohere Transcribe (English) | CPU | CPU | CPU | CPU | CPU |
| Read aloud · Pocket TTS / Supertonic 3 | CPU | CPU | CPU | CPU | CPU |
| Translation · Firefox Translations | CPU | CPU | CPU | CPU | CPU |
| Translation · Tencent HY-MT 2 | CPU / Metal | CPU / CUDA* | CPU | CPU / CUDA* | CPU |
* CUDA requires the optional NVIDIA sidecar on Windows or Linux x86-64. Installing it does not accelerate the CPU-only families. Metal/CUDA entries identify available backend paths, not certification of every model on every GPU.
Qwen3 ASR offers managed 0.6B and 1.7B choices using the same batch/backend paths. Model language coverage varies. See model and hardware support for package boundaries, other GPUs, and validation coverage.
Getting started
- Install Speech Kit from Community Plugins.
- Follow the setup wizard to install the native engine and a speech model.
- Select Try dictation now, or use the ribbon, command palette, or a hotkey. To choose a status-bar control, open Settings → Speech Kit → Advanced → Customize tools.
Dictation, local file transcription, translation, and read aloud require no account, API key, usage credits, or cloud service. Once their models are installed, they continue working offline. YouTube caption import requires a connection to YouTube.
Optional AI text tools are separate. In Settings → Speech Kit, enable LLM features, then choose a provider and model under Provider and model. Use the sidebar for daily transform controls. See provider setup.
Language support
Each feature is served by a different model, so coverage is tracked per feature rather than as a single list.
| Language | Transcription | Live dictation | Read aloud | Translation | Interface |
|---|---|---|---|---|---|
| English, Spanish, German, French, Portuguese, Italian, Dutch, Japanese | ✅ | ✅ | ✅ | ✅ | ✅ |
| Croatian | ✅ | ✅ | ✅ | — | ✅ |
| Serbian | ✅ | — | — | — | — |
✅ supported · — not yet available
Coverage depends on the selected model: Whisper Large V3 Turbo covers the transcription languages above, while English models support English only. Multilingual live models do not currently cover Serbian. Translation coverage depends on the selected model. Firefox Translations covers English-anchored directions; Tencent HY-MT 2 supports all-to-all translation among 38 languages, including languages outside the table above.
Local-first, private by default
Speech Kit works without accounts, subscriptions, or required cloud services.
- Your media stays on your machine. Dictation, local file transcription, read aloud, and translation run locally and continue working offline once their models are installed. YouTube caption import retrieves text from YouTube without downloading the video.
- Local features need no account or API key. Optional remote providers may require an account, API key, or usage fees.
- LLM tools are optional. Add flexible language processing to your workflow using a local model or a remote provider you choose. Text leaves your device only when you explicitly use a remote provider, and audio is never uploaded.
- Choose what works for you. Install high-quality models suited to your language, hardware, and workflow.
- Transparent and open. Downloads are explicit, third-party licenses are documented, and Speech Kit is open source.
Support development
If Speech Kit is useful to you, please support development:
Development and project links
Speech Kit pairs a TypeScript plugin with a Rust native sidecar. See CONTRIBUTING.md for its architecture, setup, and development workflow.
Community Plugin · Latest release
Third-party component and model licenses are documented in THIRD_PARTY_NOTICES.md. Model details link to each license; some models require you to review terms before installation.