Image to Markdown
 Johannes Kaindl1k downloads
Transcribe the images and PDFs in a note to Markdown with a local vision LLM — fully offline, non-destructive, streaming into the sidebar.
- Overview
- Scorecard
- Updates56
🇬🇧 English · 🇩🇪 Deutsch
Transcribe images and PDFs in a note to Markdown with a local vision LLM — fully offline, non-destructive, streaming live into the sidebar.
Features
- Transcribes images and PDFs embedded in a note via any OpenAI-compatible local vision model
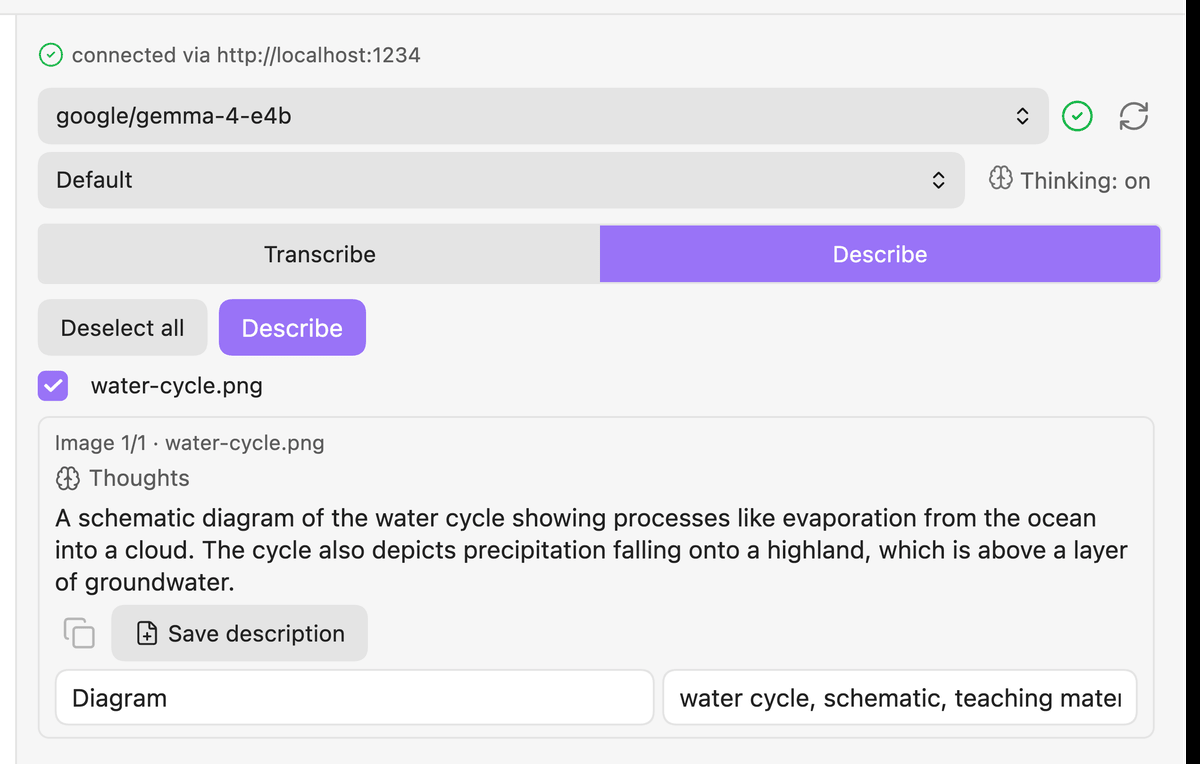
- Describe mode — a "Describe" switch next to "Transcribe" generates a description instead of a transcript, ideal for text-sparse images (photos, diagrams, whiteboards) so you can find them again through search; non-destructive, shows image + description together with an editable category (from a configurable taxonomy) and free tags; a transcript and a description for the same image coexist independently
- Refine with feedback — give a transcript card prose feedback ("this table as GFM", "wrong heading level") and the model rewrites it; a conversational, scrollable per-card history with visible thinking per round and free choice of which version to write; works after the note has already been written too (goes through the diff gate below)
- Streaming live into a sidebar — watch the Markdown appear as the model generates
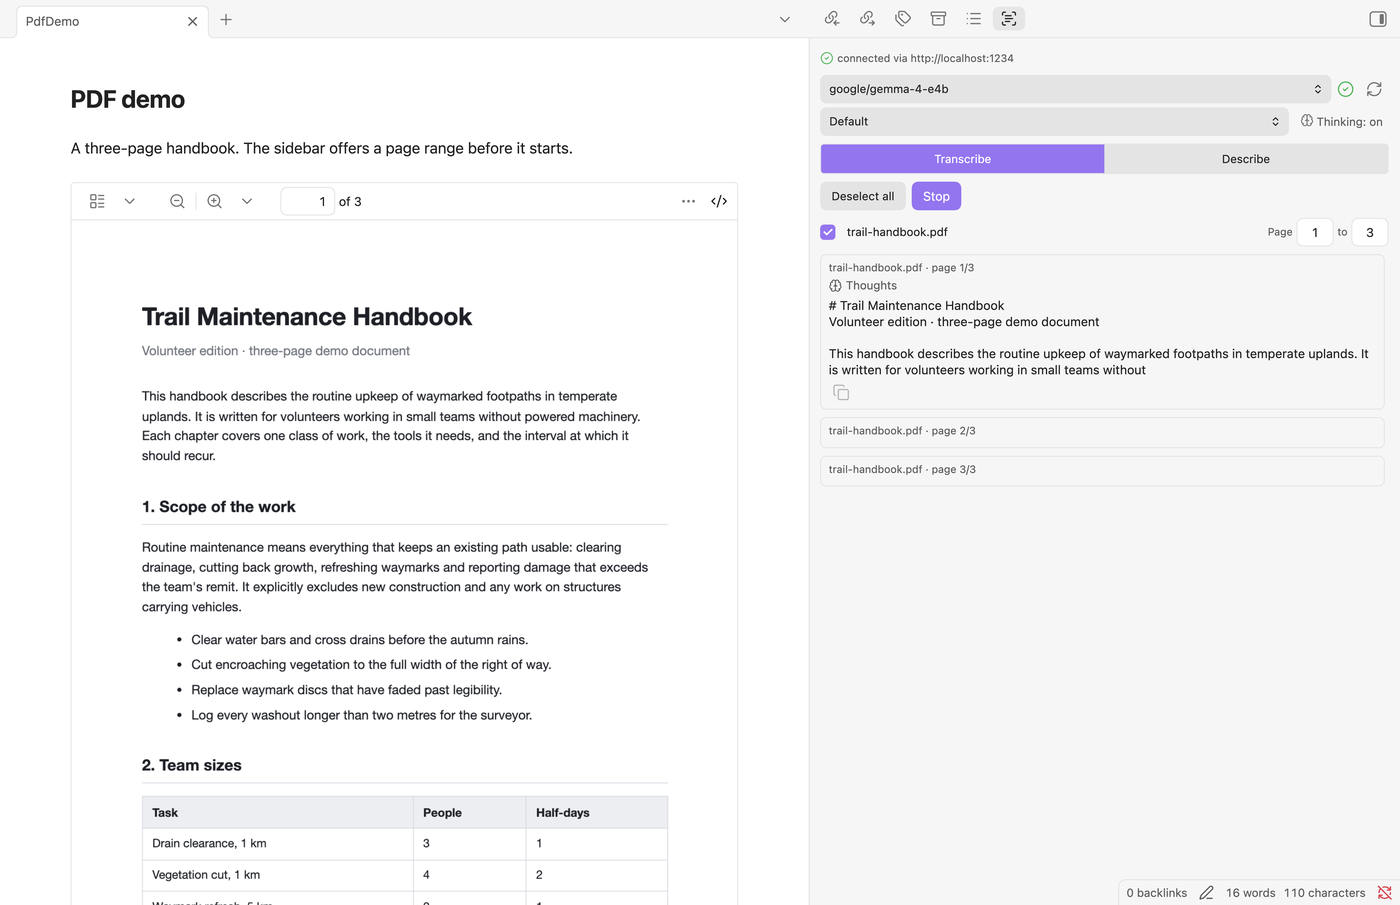
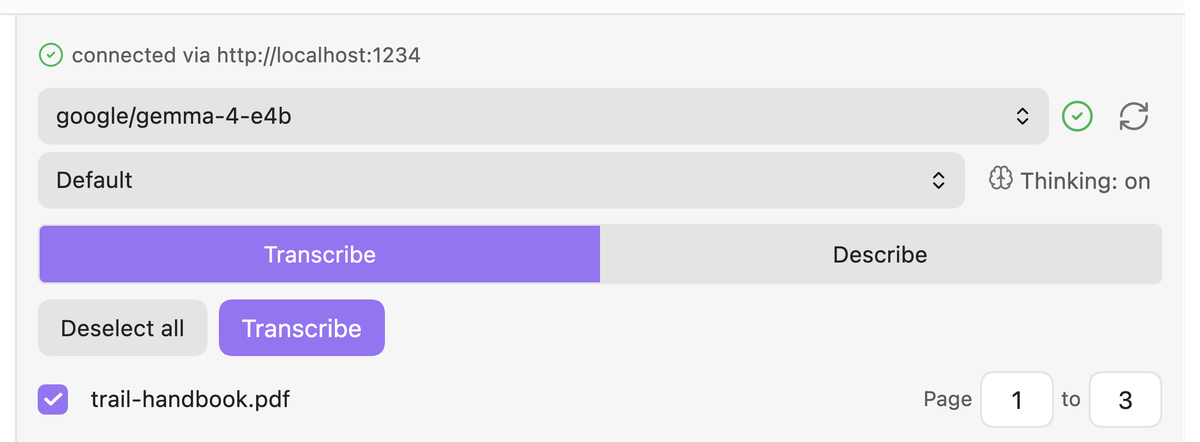
- PDF page ranges — pick which pages to transcribe; pdf.js is bundled, fully offline
- Born-digital PDFs — pages with a real text layer are sent to the model as exact text (not an image) to format as Markdown: faster and without OCR errors; scanned/figure pages fall back to the vision model. Toggle in settings
- Idempotent — one transcript note per source, no duplicates; re-transcribe is opt-in
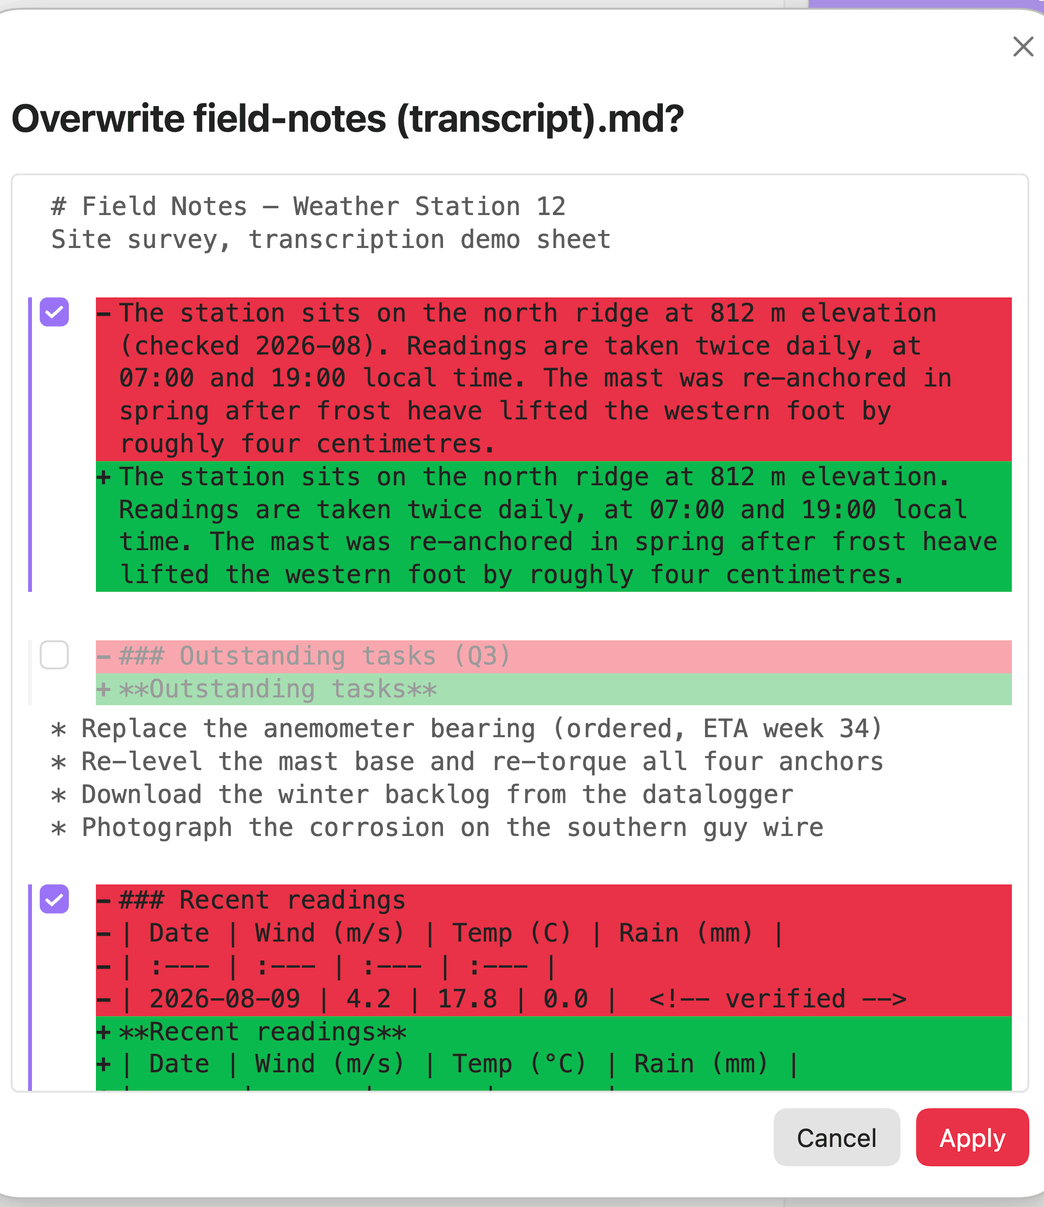
- Diff before overwriting — the one destructive operation (opt-in re-transcribe) shows a line-by-line diff first, with a checkbox per changed hunk (all on by default) so you can keep some old lines and take some new ones; in-session retries skip the prompt
- Results survive note switches — a finished, not-yet-applied sidebar result survives switching notes, collapsing the sidebar, or closing the view within the same session; a "Discard results" button clears it explicitly
- Bilingual — Obsidian's language setting (English / Deutsch) drives the UI automatically
- Non-destructive — source notes are never overwritten; embeds are replaced, originals untouched
- Standalone files — open a PDF or image directly in Obsidian and the sidebar treats that file as the source, no surrounding note required
- Prompt presets — a sidebar picker next to the model: a "Default" preset (your editable prompt) plus fixed modes for tables → Markdown, handwriting, math → LaTeX and source code; the choice is sticky. With a local vision model the prompt is the main quality lever. (Need an image description instead? Use Describe mode above.)
- Endpoint fallback list — configure an ordered list of Vision endpoints, each with an optional API key and its model (the vision-capable one, e.g. Qwen2-VL; a dropdown filled from the endpoint, a text field while it is offline) (kept in Obsidian's keychain, not in
data.json); the plugin pings them in order and uses the first reachable one automatically, so a single synced config works across devices, networks and hosted providers - Thinking level — a dropdown next to the model picker sets how much a hybrid model reasons, to skip the wait; sticky, off by default for new installs (existing settings are kept); models that can't be turned off start the list at "Low" and send that lowest level. Details and per-model sampling values live under Settings → Request
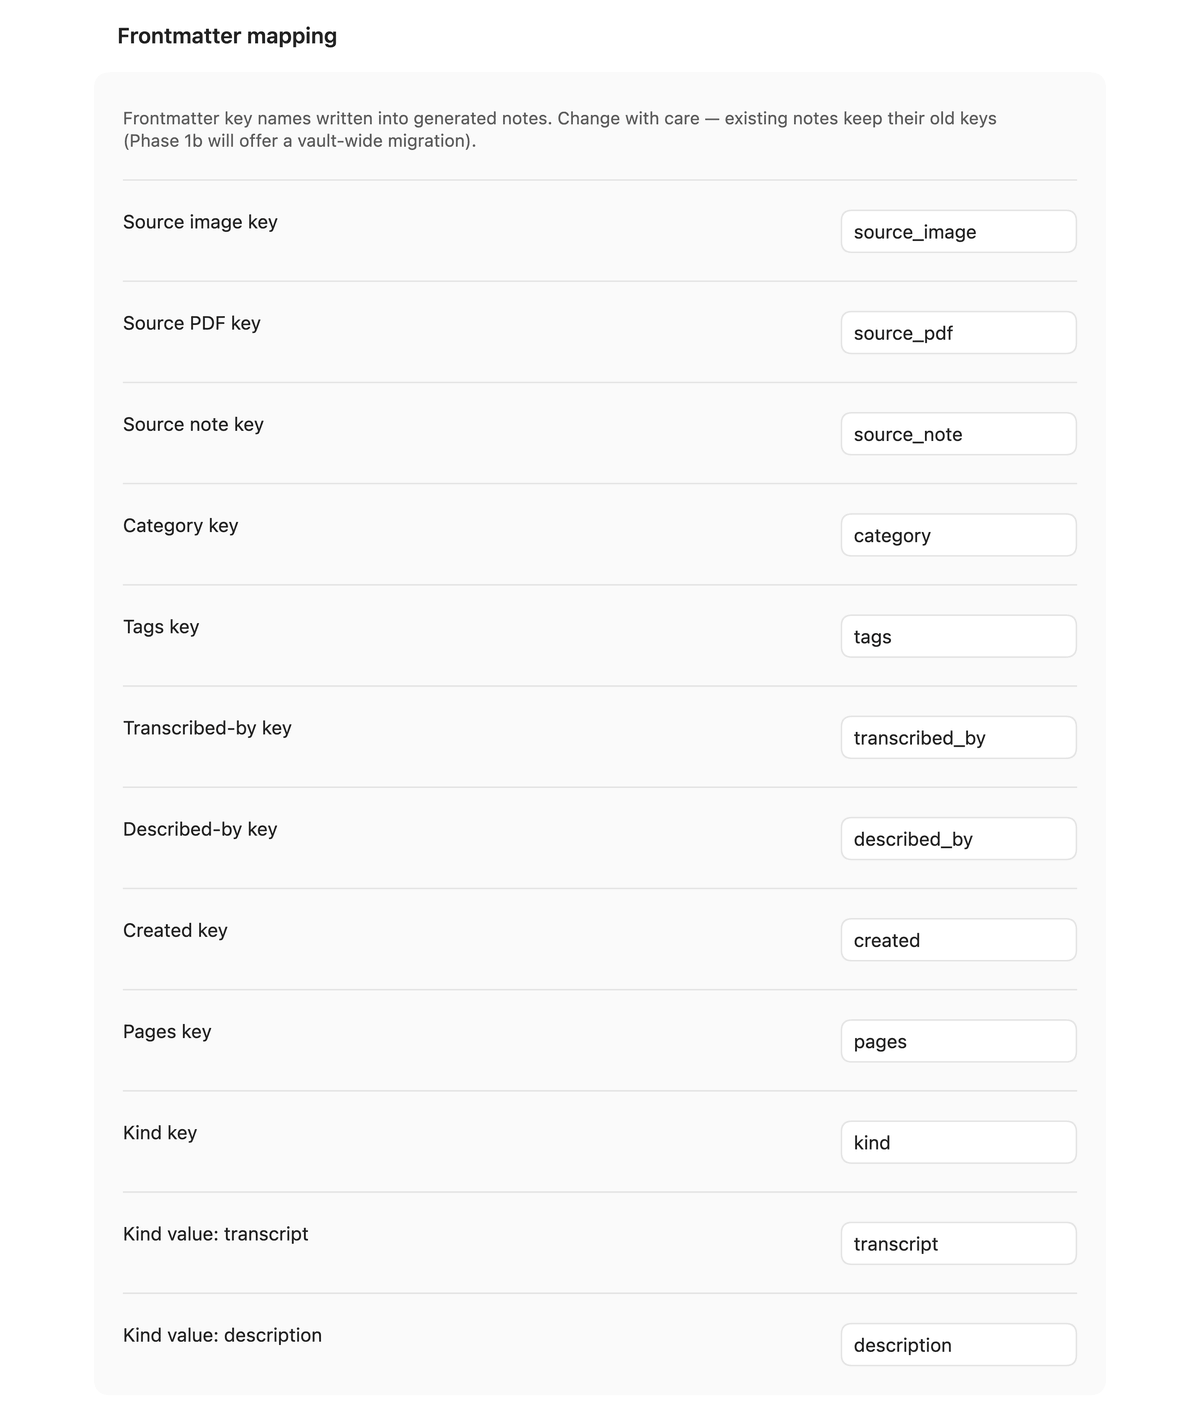
- Configurable frontmatter mapping — every frontmatter key written into generated notes (and the
typevalue) can be remapped to your own vault schema, consistently across transcript, PDF and description notes
Screenshots
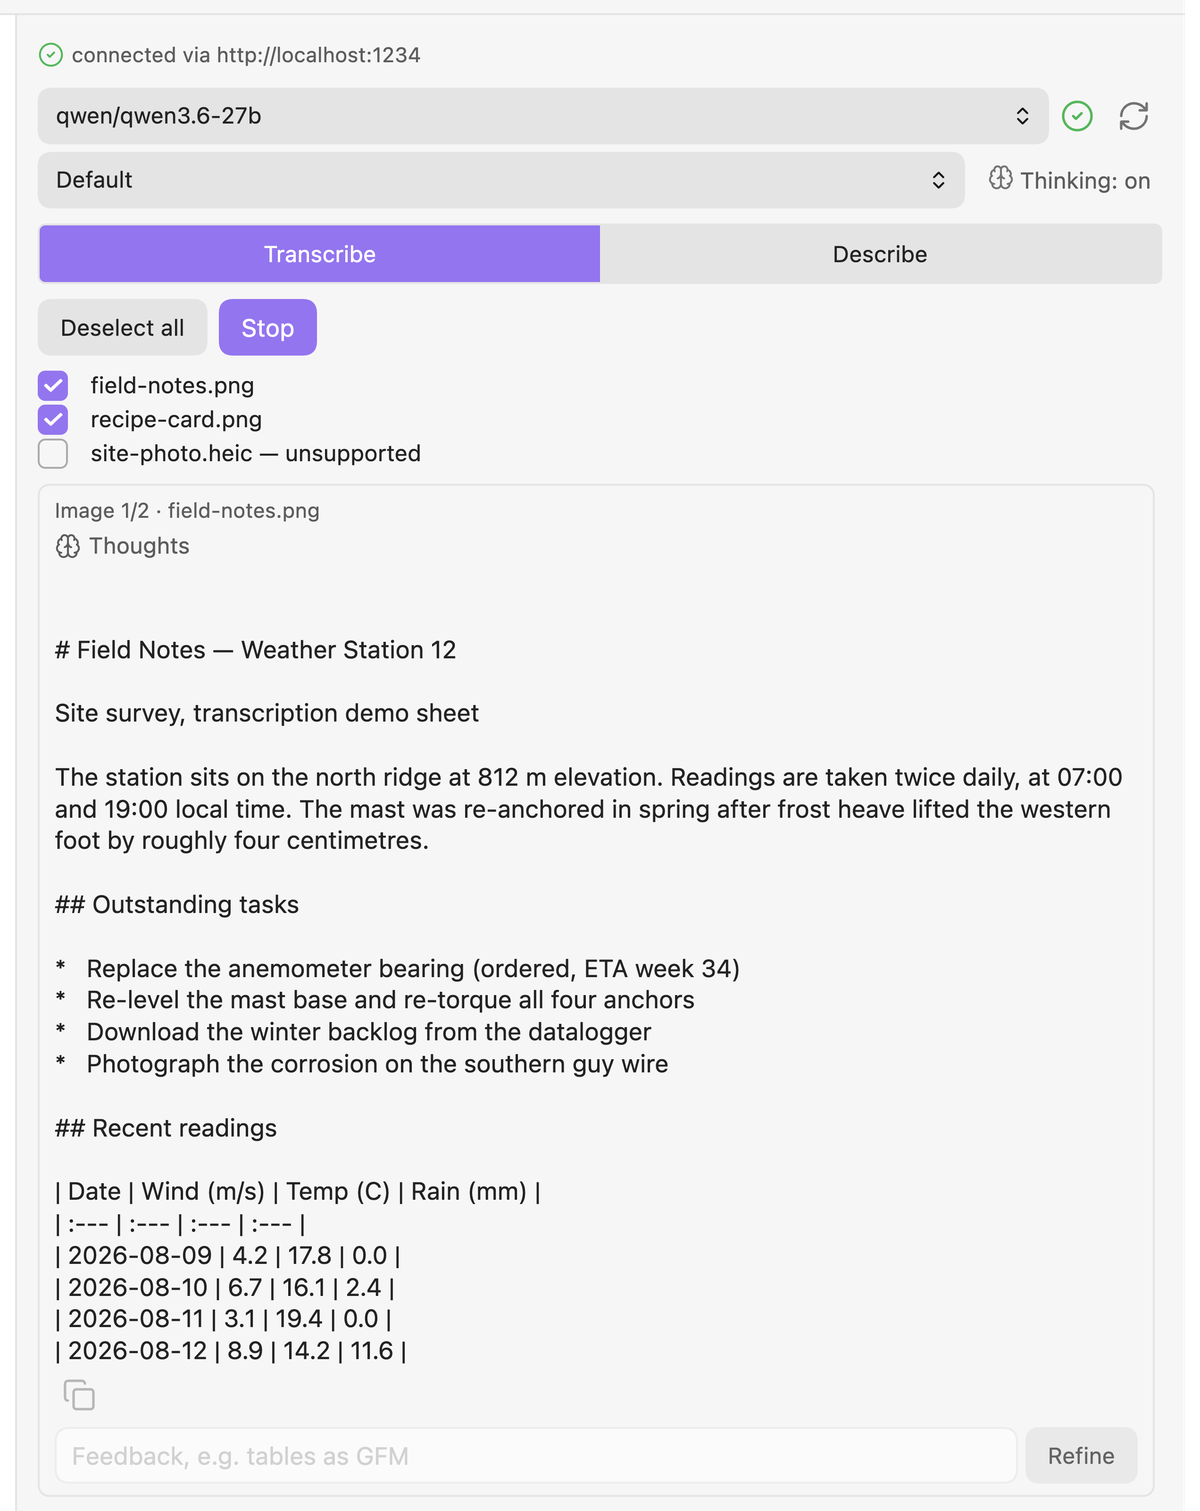
Streaming into the sidebar — one card per image with the model's thinking block and a copy button:
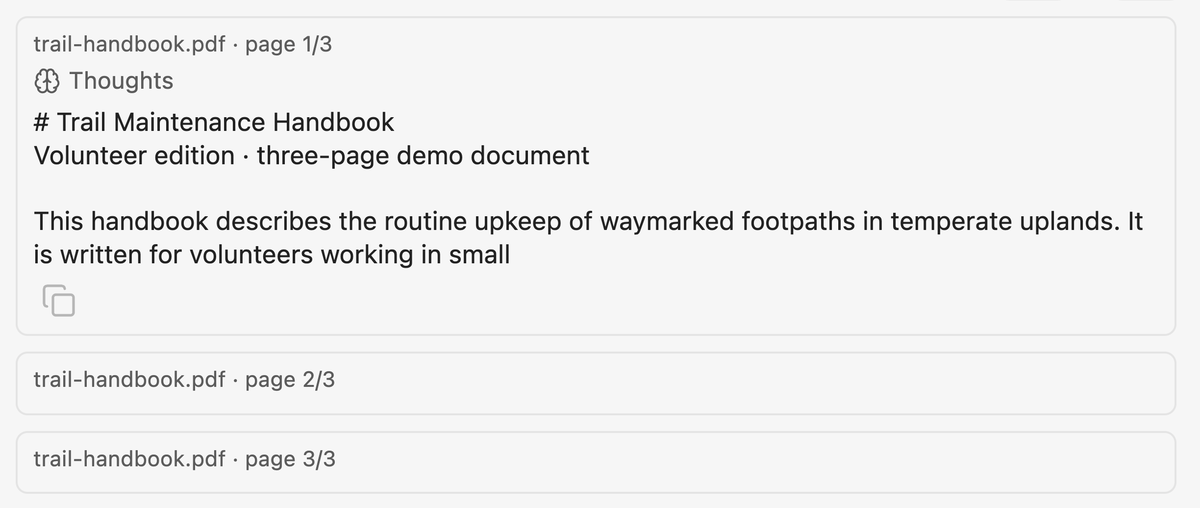
PDFs — pick a page range, then watch one card per page fill up:
Describe mode — for images that carry no text worth transcribing:
Refine with feedback — talk the transcript into shape without starting over:
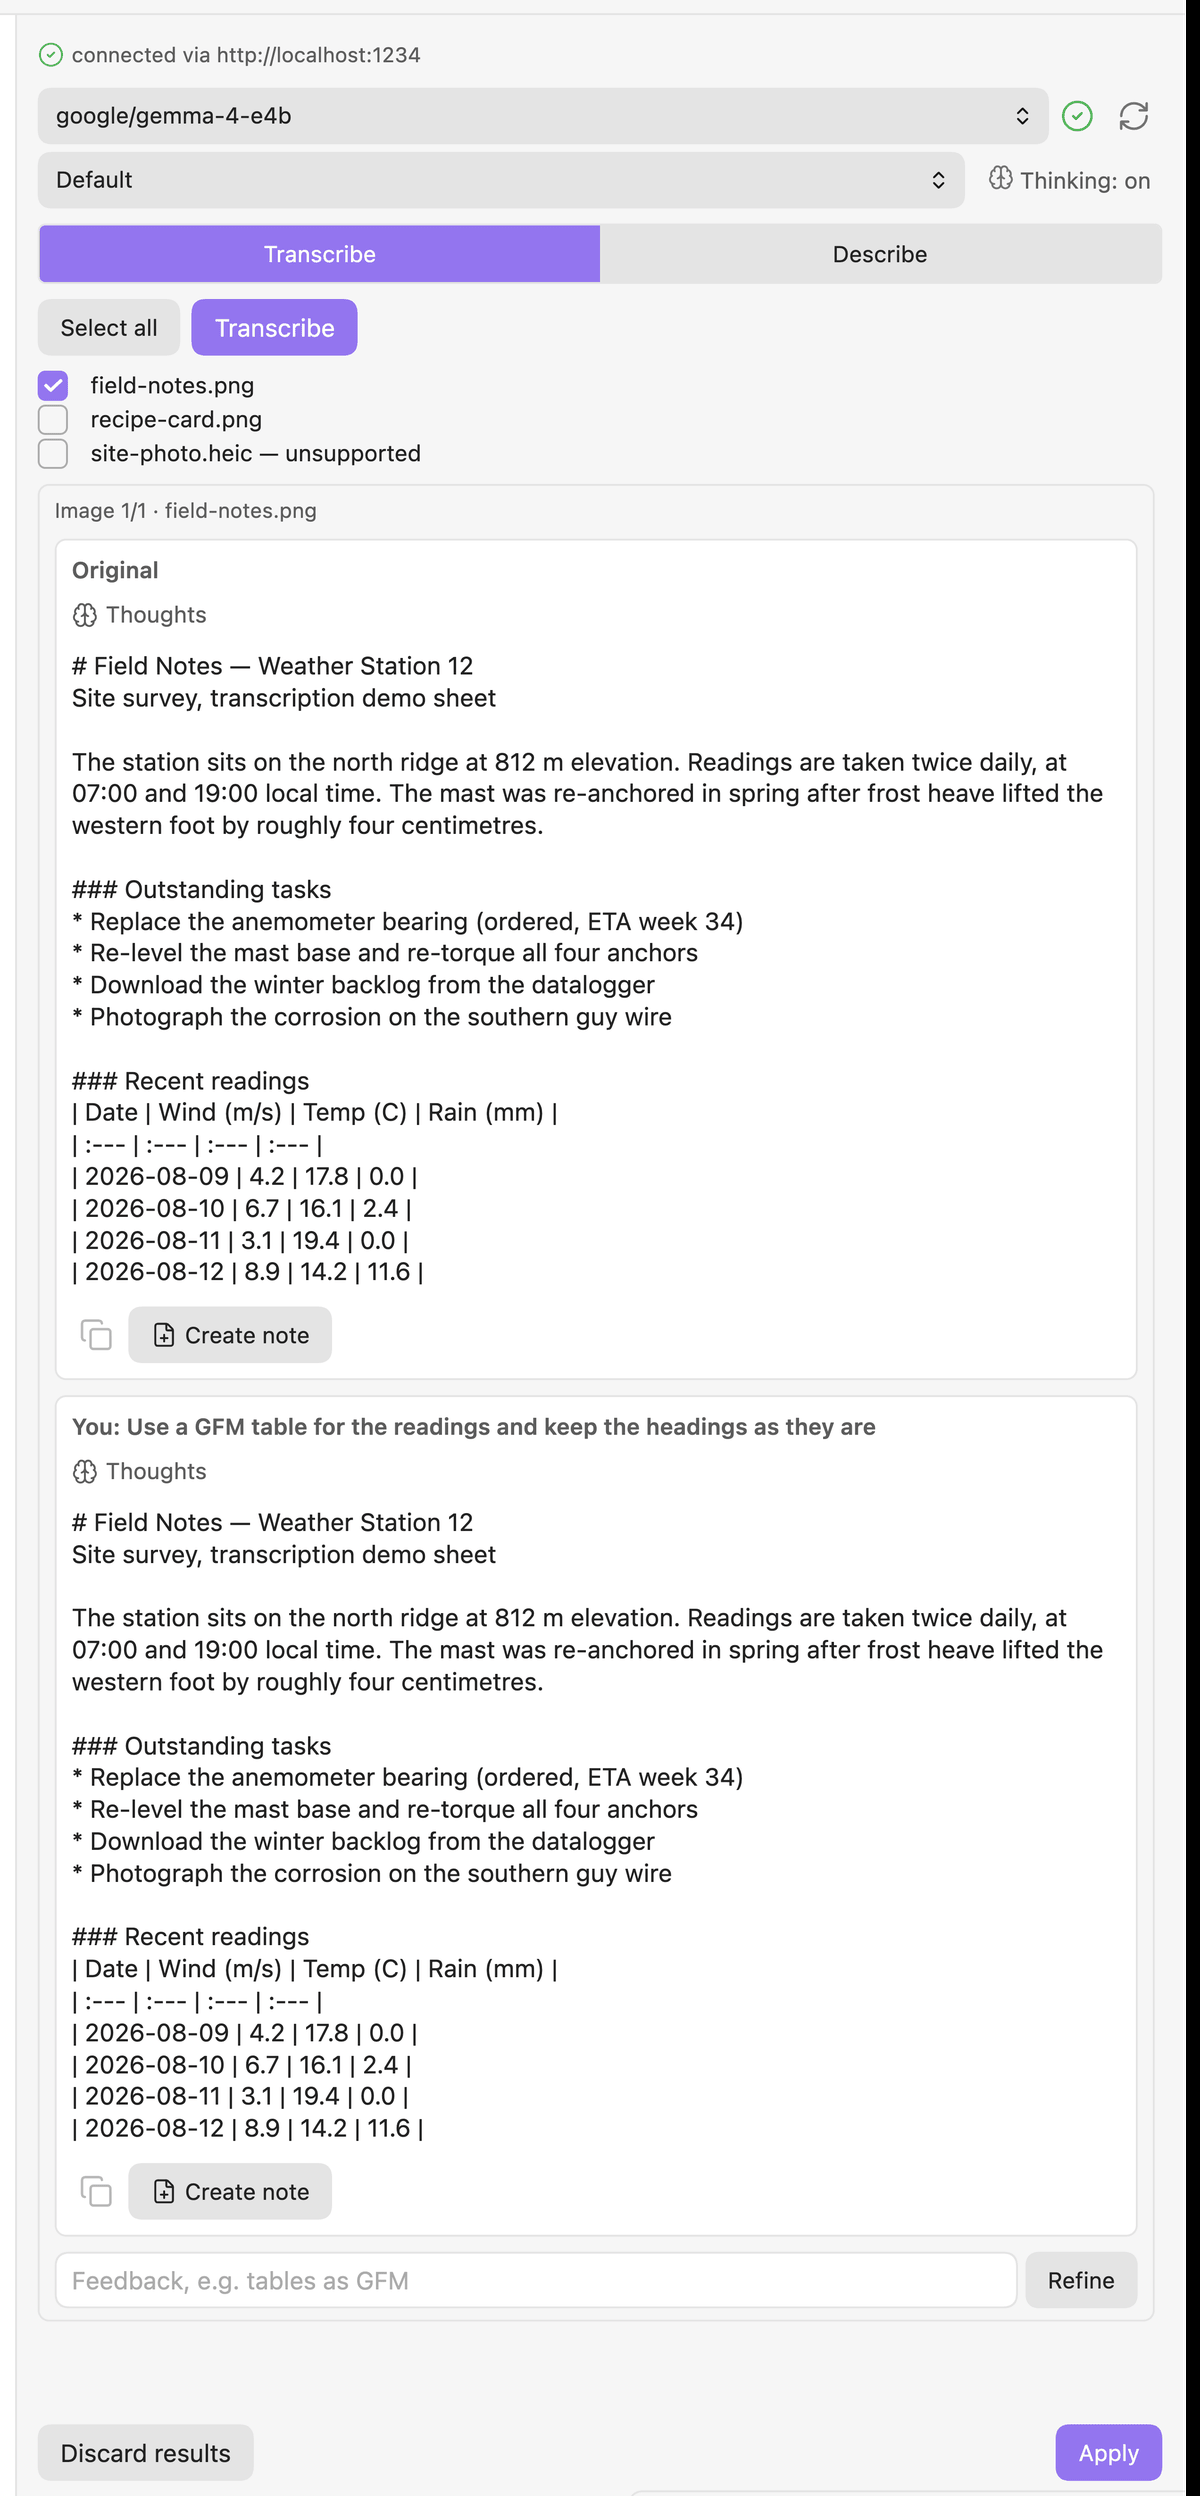 Click the preview for the full-resolution screenshot.
Idempotent — an already-transcribed source is marked instead of silently duplicated:

Diff before overwriting — the one destructive operation asks first, hunk by hunk:
Thinking toggle — skip a big reasoning model's wait when you don't need it:
In detail
Image to Markdown turns the embedded images and PDFs of an Obsidian note — scans, screenshots, photographed pages — into editable Markdown using an OpenAI-compatible vision model that runs on your own machine. Nothing leaves your computer, and your source note is never overwritten: each image or PDF gets its own transcript note, and the original embed is simply replaced by an embed of that new note.
Sidebar view. A ribbon icon (
scan-text, label "Image → Markdown") opens the "IMG → MD" view. It lists every embedded image of the active note as a checkbox list — all preselected, with unsupported formats disabled. The "Transcribe" button streams the vision model's answer live into one card per image, including an expandable thinking block for reasoning models and a copy button. Each card has a "Create note" button, plus a footer "Apply" button once at least one card is done. Cards are read-only and show the raw Markdown pre-wrapped. After a transcript is written, the handled image drops out of the list on the next scan.Describe mode. A mode switch next to the sidebar's model row — "Transcribe" / "Describe" — swaps what the run button does: instead of pulling text out of an image, "Describe" generates a description, ideal for text-sparse images (photos, diagrams, whiteboards) so you can find them again through search even though they contain no text. The result is non-destructive and shows the image together with its description on one card, with an editable Category (drawn from a configurable taxonomy, offered as a datalist) and free-form Tags — both editable before you click "Save description". A transcript and a description for the same image coexist independently.
Refine with feedback. Once a transcript card is done, type prose feedback into the "Refine" field (placeholder "Feedback, e.g. tables as GFM") — "this table as GFM", "wrong heading level" — and the model rewrites the whole document. Each card keeps a conversational history (the model sees the original plus the rounds the version you refine builds on — pick an earlier version and refine, and later rounds you stepped back from are not sent), rendered as a scrollable log with the original transcription as its first, equal entry, a per-round expandable thinking block, and a [Copy] [Create note]-style action pair on every version so you can freely pick which one to write. The footer offers "Discard results" on the left and a colored "Apply" button on the right that writes the latest version. Text-only (no image re-grounding), fully in-session, and — once a note has already been written — re-writing goes through the same diff gate described below.
PDF transcription (sidebar). Embedded PDFs appear in the same sidebar alongside images. Select the page range you want (default: all pages), then click "Transcribe" — each page is rendered via the bundled pdf.js and transcribed page-by-page. One transcript note is created per PDF and the PDF embed is replaced, exactly like an image. Page limits (
pdfMaxPages) and a mobile-friendly render scale (pdfRenderScale, a 1.0–4.0 slider) keep memory usage in check, and the page separator in the merged note (pdfPageSeparator) is configurable. No external CDN — pdf.js is bundled fully offline.Standalone file as source. When the active file is itself a PDF or image — opened directly in Obsidian, not embedded in a note — the sidebar lists it as a single entry labelled "this file" and treats it as the transcription source. The page-range picker works as usual for PDFs; images show a single card. The transcript note is placed at Obsidian's "Default location for new notes" (via
app.fileManager.getNewFileParent) because there is no source note to sit next to. The frontmatter contains nosource_notefield;source_pdf/source_image,created,transcribed_by(andpagesfor PDFs) are still written. The source file is never modified. Idempotency and override apply as usual.Truncation is recorded in the note, not just on screen. When the model stops at its token limit (
finish_reason: "length"), the sidebar card says so — and the written note now says so too, via atruncated: truefrontmatter field. The key is written only when true: its absence means "complete or unknown", because notes written before this version know nothing about their own completeness. Re-transcribing a truncated note removes the key again once the new version is complete. Like every other key, it can be remapped under "Frontmatter mapping".Backlink-based idempotency. Already-transcribed sources are detected automatically via the vault's backlink index: if a note already carries a
source_pdforsource_imagefrontmatter field that resolves to the source file, the sidebar shows "✓ transcript exists" with an "open" link for that entry instead of re-transcribing. Such entries start unchecked; re-tick the row's checkbox and transcribe to force a new transcription (the row's tooltip reads "re-transcribing overwrites it") — the existing note is overwritten while its full frontmatter (excepttranscribed_by/pages) is preserved. Overwriting itself goes through the diff-confirm step described next.Diff before overwriting. The one operation that replaces existing content — an opt-in re-transcribe that overwrites an already-existing transcript note — is gated: a native modal titled "Overwrite <file>?" shows a line-by-line diff of old vs. new, with a checkbox per changed hunk (all ticked by default) so you can keep some old lines and take some new ones; ticking every hunk off is a no-op and nothing is written. Confirm with "Apply" or back out with "Cancel". The
+/-markers are readable without relying on color (accessible for red-green color blindness). In-session retries — e.g. filling in a PDF page that failed the first time — skip the prompt entirely, and the gate compares the note's actual on-disk content, so it still fires correctly if you hand-edited the note between two overwrites in the same session.Results survive note switches. A finished, not-yet-applied sidebar result is no longer lost when you switch to another note, collapse the sidebar, or open a different view in between — come back to the same source within the same session and the pending result is still there (remembered per source file). A "Discard results" button clears it explicitly; re-transcribing the same source replaces it. Gone after an Obsidian restart (the source file is still there, so re-transcribing is one click away).
Endpoint fallback list. Instead of a single Vision endpoint, the plugin accepts an ordered list. On each resolve (sidebar refresh, or after a failed call with one automatic retry) it pings the endpoints in order and picks the first reachable one. The active endpoint is marked in the settings and shown in the sidebar status line as "connected via <endpoint>". The settings tab renders a dynamic field per entry — an empty trailing field acts as "add new"; clearing a field and leaving it removes the entry. Each field shows its own reachability icon (circle-check / circle-x / loader) plus accessible title text. A single synced
data.jsontherefore works on all your devices: putlocalhost:1234first (the machine running LM Studio), then a LAN IP as fallback (reachable from phone/tablet via WireGuard). Each entry can carry its own API key (a password field next to the address), so a local server and a hosted provider can sit in the same chain; without a key noAuthorizationheader is sent at all. Keys live in Obsidian's keychain (Settings → Keychain), not indata.json: a key from an older version moves there automatically the first time the endpoints are resolved, and a synceddata.jsonno longer carries it — check the key field on each device. Migration is automatic: both an existingvisionEndpointkey and a plain string list indata.jsonare silently promoted to the current form — no manual action needed.LLM Endpoint Manager. If the LLM Endpoint Manager plugin is installed, the endpoints (and their keys) come from it instead: the settings tab then offers an endpoint and model choice and a button to copy your local endpoints into the manager, and your local list stays as a fallback for when the manager is off. If the manager reports no endpoint, there is no fallback to the local list. Claude (Anthropic API) is an opt-in: if the manager has a Claude entry, pick it in the model row to send your images to Anthropic; "Automatic" never picks it, even when it is first in the manager's list.
Thinking level. A dropdown next to the model picker (brain icon, then the levels of the chosen model: Off / Low / Medium / High, for Claude up to Very high and Max) sets how much a hybrid model thinks — handy when a big reasoning model would otherwise think for a long time before you get a result. The choice is sticky (default: off; existing installs keep their previous choice). Where "off" isn't possible (e.g. gpt-oss/harmony, Gemma 4 in LM Studio) the list starts at Low, and the plugin sends that lowest level; a Claude model with a stored "off" gets the model's own default level. Models the plugin cannot place show no level dropdown unless the server is LM Studio or Open WebUI (then the generic four levels). The model's full name is in the dropdown's tooltip.
Configurable frontmatter mapping. Every frontmatter key written into generated notes — plus the
typevalue itself — can be remapped to your own vault's schema under "Frontmatter mapping" in settings (e.g.kind→type), consistently across transcript, PDF and description notes. Changing a key later offers to migrate existing notes vault-wide — a per-note diff preview with a three-way confirm (migrate & apply / apply without migrating / cancel).Bilingual UI (English / Deutsch) — every user-facing string follows Obsidian's language setting; English is canonical, German is provided automatically. The language is detected once when the plugin loads (reload to switch).
Command "Transcribe images in the active note" (id
transcribe-active-note) — batch transcription without opening the sidebar.Command "Open sidebar" (id
open-sidebar) — opens the sidebar view.Editor context-menu entry "Image → Markdown" (icon
scan-text) — transcribes only the image under the cursor. (PDFs are not supported via context menu — use the sidebar.)
Reasoning models that emit reasoning_content in the stream, or inline <think> tags, get their thoughts collected into the expandable thinking block. Reasoning is ephemeral — it is shown to you but never added to the LLM history.
Requirements
- Obsidian 1.11.4+ (desktop or mobile) — API keys are kept in Obsidian's keychain, which needs that version.
- An OpenAI-compatible local server running a vision-capable model (e.g. LM Studio). New to local LLMs? The local LLM setup guide walks you through server, model and mobile access end to end. The endpoint and model are configured in the plugin settings. Nothing leaves your machine: offline-first, no cloud, no VPN required.
Install
Community plugins (recommended)
Search for Image to Markdown in Settings → Community plugins → Browse, then click Install and Enable.
Manual
Download main.js, manifest.json, and styles.css from the latest release and place them in <vault>/.obsidian/plugins/image-to-markdown/, then enable the plugin under Settings → Community plugins.
From source
git clone https://git.jkaindl.de/jkaindl/image-to-markdown
cd image-to-markdown
npm install
npm run build   # produces main.js
Then copy main.js, manifest.json, and styles.css into <vault>/.obsidian/plugins/image-to-markdown/ and reload Obsidian.
Usage
- Point the plugin at your local vision server (see Configuration below) and make sure the model is loaded.
- Open a note that contains embedded images or PDFs.
- Click the ribbon icon "Image → Markdown" (or run the command "Open sidebar") to open the "IMG → MD" sidebar. The embedded images and PDFs appear as a preselected checkbox list; unsupported formats are disabled.
- Click "Transcribe". Each selected image or PDF gets a card that fills live with the streamed Markdown. For reasoning models, expand the thinking block to watch the model reason; use the copy button to grab the raw Markdown.
- Click "Create note" on a single card, or use the footer "Apply" button to write every finished transcript at once. Each image or PDF becomes one transcript note, and its embed in the source note is replaced by an embed of the new note.
Prefer to skip the sidebar? Run the command "Transcribe images in the active note" to batch-transcribe the active note. Or right-click an image in the editor and choose "Image → Markdown" to transcribe only the image under the cursor.
Configuration
Open Settings → Community plugins → Image to Markdown. The settings live under the heading "Vision (Image → Markdown)".
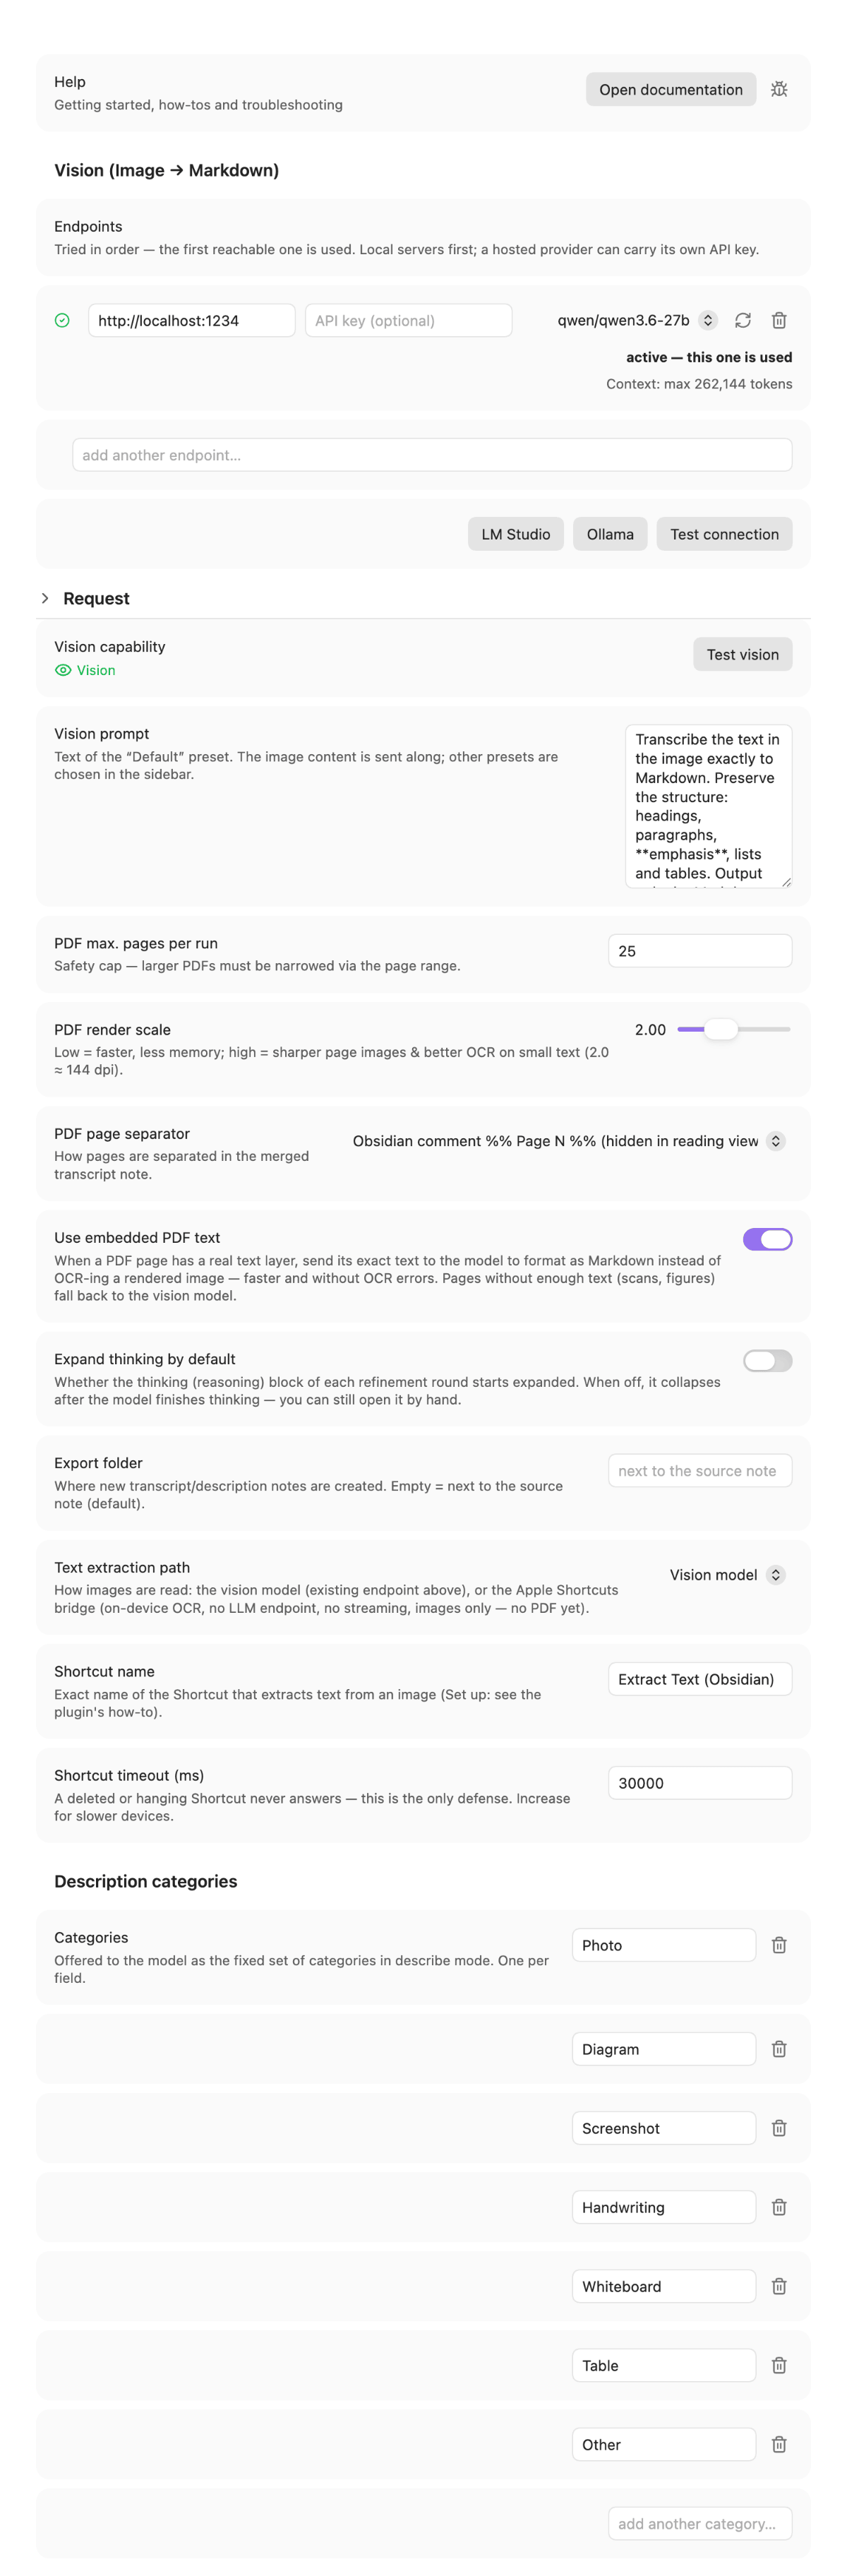 Click the preview for the full-resolution screenshot.
| Setting | What it does | Default |
|---|---|---|
| Vision endpoints | Ordered list of OpenAI-compatible servers, each with an optional API key (stored in Obsidian's keychain). The plugin pings them in order and uses the first reachable one; a row can be moved to the front with "Try this endpoint first". | [{"url": "http://localhost:1234"}] (LM Studio's port; an MLX server listens on :8080) |
| Vision prompt | The instruction sent to the vision model; freely editable text area. The shipped default is localized (English or German, following Obsidian). | "Transcribe the text in the image exactly to Markdown. Preserve the structure: headings, paragraphs, emphasis, lists and tables. Output only the Markdown, no comments." |
| PDF max. pages per run | Safety cap on the number of transcribed PDF pages per run — larger PDFs must be narrowed via the page range. Hard-capped at 500. | 25 |
| PDF render scale | Render resolution of PDF pages before OCR (1.0–4.0 slider, step 0.5). Low = faster, less memory; high = sharper page images & better OCR on small text (2.0 ≈ 144 dpi). On mobile it is clamped to 1.5 to protect against OOM. | 2.0 |
| PDF page separator | How pages are separated in the merged transcript note. Five options: Obsidian comment %% Page N %% (hidden in reading view), heading ## Page N, horizontal rule ---, page break (HTML, for export), or none (seamless text). |
Obsidian comment %% Page N %% |
| Use embedded PDF text | For born-digital PDF pages with a real text layer, send the exact text to the model to format as Markdown instead of OCR-ing a rendered image — faster and without OCR errors. Scan/figure pages fall back to the vision model. | On |
| Expand thinking by default | Whether each refinement round's thinking (reasoning) block starts expanded. Off = it collapses once the model finishes thinking (you can still open it by hand). | Off |
| Description categories | The fixed set of categories offered to the model in Describe mode (one per field, add/remove like the endpoint list). | A built-in list in the interface language of the time you installed (Photo, Diagram, Screenshot, Handwriting, Whiteboard, Table, Other), editable; a saved list is never rewritten |
| Frontmatter mapping | Remap every frontmatter key written into generated notes — and the type value — to your own vault schema (e.g. kind → type), consistently across transcript, PDF and description notes. Changing a key later offers a vault-wide migration of existing notes (per-note diff preview + double confirmation). |
The plugin's default keys |
Endpoint tip: enter the base URL without a trailing /v1 — the client appends /v1 itself. (normalizeEndpoint strips a trailing /v1 and slashes, so both forms are accepted; a doubled …/v1/v1/… path would otherwise silently return an empty transcript.)
Next to the input fields the settings tab shows a connection status indicator with a "Test connection" button, and a "Vision capability" row with a "Test vision" button that confirms whether the selected model can actually read images — see the manual reference.
How it works
For each selected image, the plugin builds a multimodal chat-completions request — the image lives in the content array — to the configured OpenAI-compatible vision endpoint, and streams the Markdown back over SSE (content plus reasoning_content). It then writes one transcript note per image with a transcribed_by frontmatter field (the model name taken from response.model, because some servers such as LM Studio ignore the request's model field and use the loaded model instead) and replaces the image embed in the source note with an embed of the new note. The result is non-destructive and idempotent.
For PDFs, each page is rendered to a canvas by the bundled pdf.js (offline, no CDN; worker embedded as a Blob URL), converted to a PNG data URL, and sent to the same vision endpoint as a regular image. Pages stream as individual cards in the sidebar, and one transcript note is produced for the whole PDF.
The architecture and module layout are documented in docs/internal/architecture.md.
Supported image formats
Sent to the model: PNG, JPG, JPEG, WebP, GIF. Recognized but skipped (with a notice): BMP, HEIC, HEIF. HEIC/HEIF is the iOS default and is rejected by vision models — set iOS to "Most Compatible" ("Maximal kompatibel") or convert the image first. When an image is skipped you'll see a notice such as: Format .heic nicht unterstützt (HEIC? iOS auf „Maximal kompatibel").
Gotchas
- The
/v1footgun: an endpoint with a trailing/v1used to produce…/v1/v1/chat/completions. LM Studio answers wrong paths with HTTP 200 plus an error body (not a real HTTP error) →res.okis true, the stream is empty → a silently empty transcript. Fixed bynormalizeEndpoint()(strips a trailing/v1plus slashes). - LM Studio ignores the request's
modelfield and uses whatever model is loaded — the model actually used is read fromresponse.modeland lands in the transcript note'stranscribed_byfrontmatter. - Vision endpoint default is
:1234(LM Studio); an MLX server listens on:8080. Only a fresh install gets the default; a saved list is never touched.
Documentation
The full documentation follows the Diátaxis framework — start at the documentation index:
- Getting started — from a local vision server to your first transcript note.
- Troubleshooting — the exact message you see, what it means, what to do.
- How-to guides — task-focused recipes (configuring LM Studio, handling HEIC, batch transcription).
- Reference — settings, commands, supported formats.
- Explanation — the non-destructive/idempotent design and the streaming mechanism.
See the changelog for release notes.
Development
git clone https://git.jkaindl.de/jkaindl/image-to-markdown
cd image-to-markdown
npm install
npm run dev     # esbuild watch
npm run build   # prod bundle → main.js
npm test        # vitest
Contributions are welcome. Please read CONTRIBUTING.md for the workflow (test-driven, main always green, feature work in feat/<name>, Conventional Commits) and AGENTS.md for the architecture and module conventions. The canonical repository lives on Forgejo; GitHub (johannes-kaindl/image-to-markdown) only receives the branch and tag when a release is published.
Security
Image data is sent exclusively to the local endpoint you configure — no telemetry, nothing to the cloud or third parties. The trust anchor is the local server you control.
Please don't report security vulnerabilities as a public issue — email [email protected] instead (PGP welcome). See SECURITY.md.
Related
vault-rag — the sister plugin, home of the RAG core (related notes, semantic search, chat). Image to Markdown was split out of vault-rag 0.2.0 on 2026-06-21 because image transcription is not RAG; the two only ever shared the SSE transport.
License
- Code: AGPL-3.0-or-later. A commercial dual-license is available on request if the AGPL copyleft does not fit your use case.
- Documentation and text: CC BY-SA 4.0.
Copyright © 2026 Johannes Kaindl.